Edition 3 · 03 / 08
What Happens Between Prompt and Answer?
The visible AI increasingly includes reasoning, retrieval, tools and checks surrounding a foundation model.
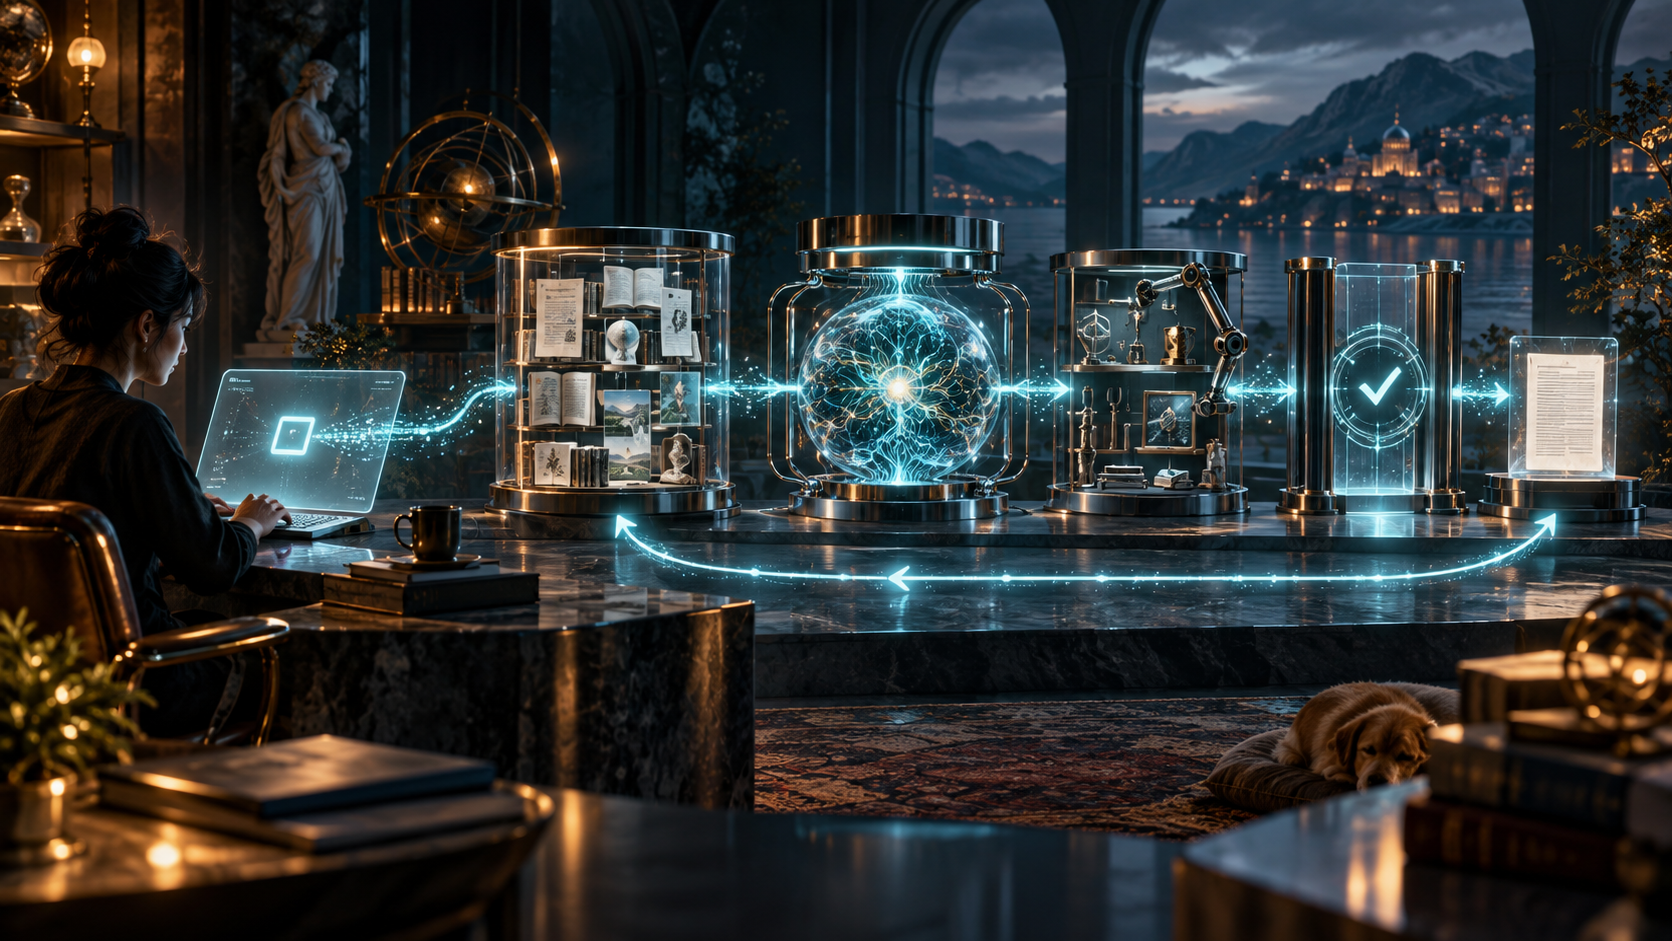
A difficult question arrives. The service searches a document store, chooses relevant passages, runs code, revises its answer and checks a result. Which part of the resulting capability belongs to “the model”?
The model remains central. But the user experiences the whole arrangement. A model without access to a current document cannot retrieve that document simply by having more parameters. A calculator can make a numerical workflow more reliable without changing the weights at all.
More work at the point of use
Inference-time computation is effort spent after training, while solving a task. It can include longer reasoning, candidate solutions, search or verification. Snell and colleagues found that allocating this effort according to problem difficulty could outperform a simpler uniform strategy on their mathematical evaluations. That is evidence for conditional gains, not a universal promise that asking a weak model to think longer reproduces every stronger model. Scaling LLM Test-Time Compute Optimally.
A useful design spends little effort on straightforward requests and more where additional computation improves the outcome. It also needs a stopping rule. Repeatedly reconsidering a wrong answer can increase cost without supplying missing evidence.
User task → relevant context → foundation model
A possible system design. Not every product uses every component.
What is documented today?
This is a disclosure snapshot checked on 18 September 2026, not a performance league table. Product capabilities and the architecture of the underlying model are different forms of evidence.
| System | Publicly documented | What this does not establish |
|---|---|---|
| OpenAI GPT-6 Astra | The API documentation exposes selectable reasoning effort and support for complex tool-based work. | A parameter count, expert layout or exact internal reasoning process. |
| Anthropic Claude Fable 5.1 | The September announcement describes coding and knowledge work, with differentiated safeguards for Fable and Mythos. | The number of experts or a causal explanation of each performance gain. |
| Google Gemini | Current cards list Gemini 3.8 Flash and Gemini 3.1 Pro, document inputs and outputs, and link their architectural dependencies. | That every Gemini variant has identical internals or an inferred parameter count. |
| Meta Muse | Meta documents Muse Spark 1.1 API access and a September Muse agent product that takes actions. | That the product’s orchestration is the same thing as a model’s internal architecture. |
Sources: OpenAI API model documentation, Anthropic’s September announcement, Google model cards, Meta’s API announcement and Muse product announcement.
It is plausible that a provider uses additional routing or internal selection. Unless disclosed, that remains an inference. Giving it an expert count or attributing a benchmark result to it would be speculation. These sources are vendor disclosures, not independent confirmation of every performance claim.
The orchestration has its own failure modes
Retrieval supplies material; context management decides what stays visible. Memory retains selected state between steps. Tools connect the model to code, browsers and external systems. Verification tests whether a result meets a criterion. Each adds opportunity and an additional place to fail.
An agent loop repeats this process until completion or a stopping condition. Several agents can divide independent work, then combine their findings. Anthropic’s research-system account describes a lead agent coordinating parallel subagents. It also makes clear that this is an engineered workflow, not simply another name for a larger model. How we built our multi-agent research system.
Our practical inference is that parallelism is most useful when tasks separate cleanly. Shared mistakes, duplicated searches and conflicting edits can consume the benefit. Ten agents agreeing with the same incorrect source are not ten independent checks. Permissions, provenance and a reliable test of completion matter as much as headcount.
Six overlapping forms of scale
The progression is a useful organising lens, not a chronology with clean boundaries:
- Parameter scaling: increase representational capacity.
- Compute and data scaling: improve the balance of model size, examples and training effort.
- Selective computation: route work to subsets of capacity.
- Inference scaling: allocate more effort to harder tasks.
- System scaling: add retrieval, tools, memory and verification.
- Agent scaling: divide and coordinate work across model instances.
Every layer still consumes physical resources. Better organisation can make computation more productive; it does not make computation free. That brings us to the constraints outside the model.