Edition 3 · 07 / 08
If Intelligence Gets Cheaper, Where Does the Value Go?
Frontier models could become intelligence foundries. Specialist models, continuity plans and governed operational experience may change what organisations pay for — and what they can preserve.
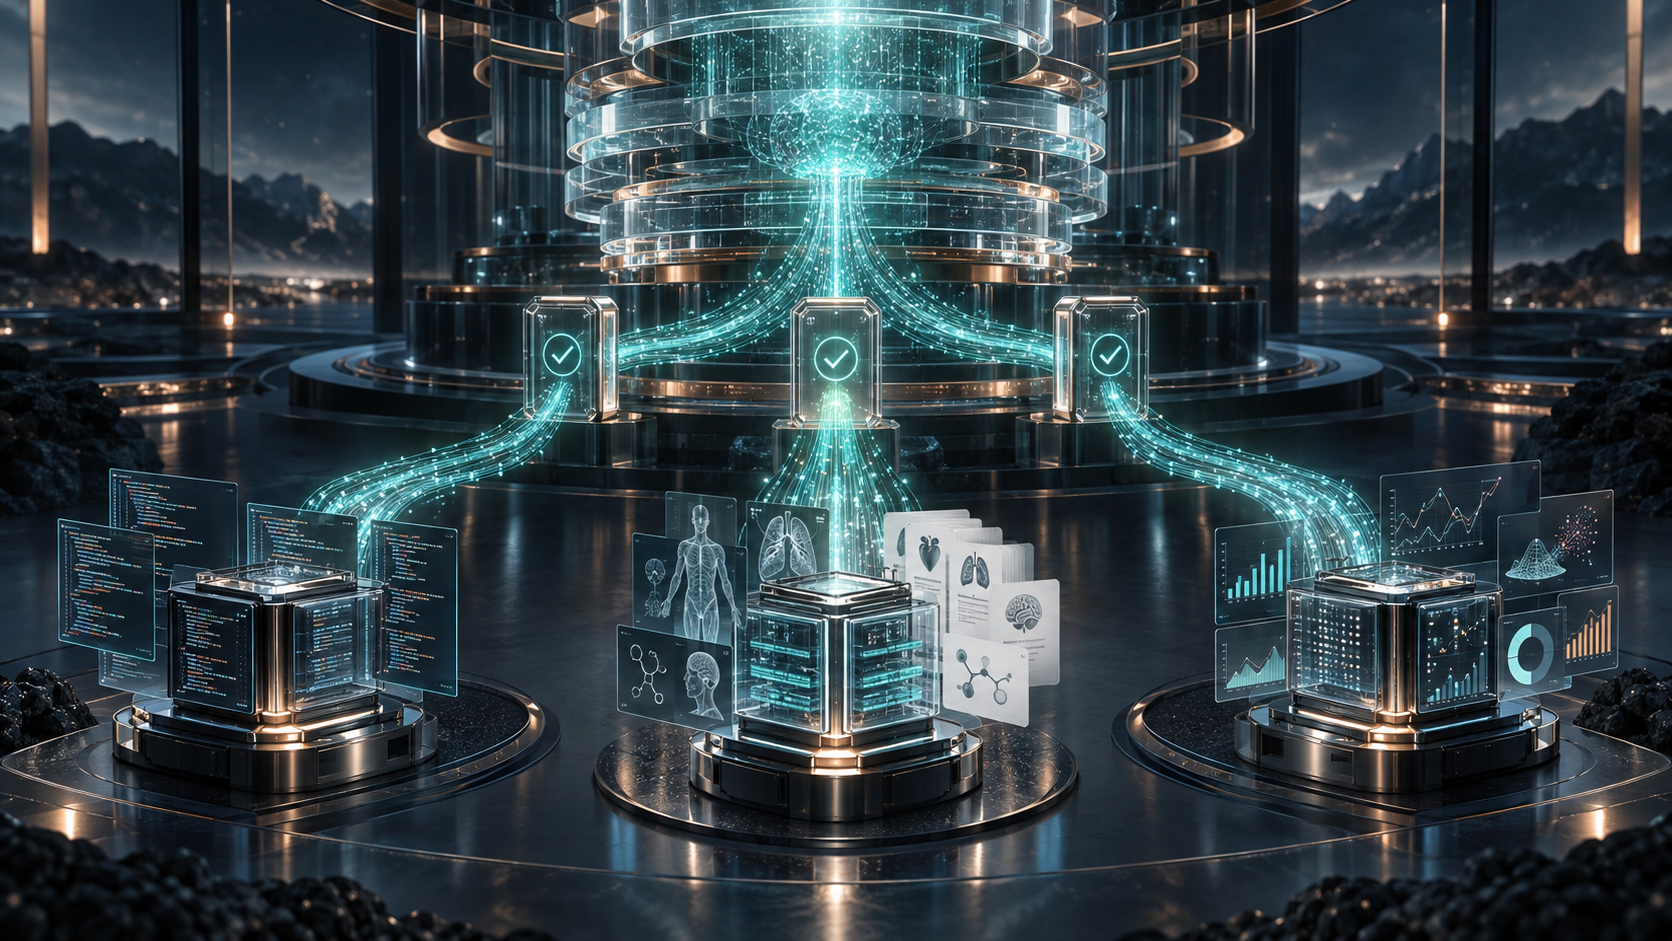
The commercial story of frontier AI is easy to draw: enormous capital buys enormous compute, which produces scarce capability, which supports subscriptions, APIs and platforms.
But scarcity is a moving target. If a cheaper system can perform yesterday’s difficult task, the original capability can remain useful while losing its pricing power. A frontier developer may need to keep discovering valuable tasks or build an advantage around the capability it already has.
For the customer, the question is equally consequential. Does each API call buy only an answer, or can permitted, carefully selected experience help build a capability that survives a change of supplier? That connects the economics of scaling to specialist models, continuity planning and the value of knowing how an organisation actually gets its work done.
Cheaper at a fixed level is not cheaper everywhere
Stanford’s 2025 AI Index reported a fall in the inference price of systems reaching a GPT-3.5-level MMLU score from $20 per million tokens in November 2022 to $0.07 by October 2024. That is more than a 280-fold reduction for a specified historical benchmark threshold. It is not a measure of every task, a claim about current frontier pricing or a direct estimate of providers’ underlying costs. AI Index, Research and Development.
The distinction is crucial. A lower token price can be offset by longer reasoning, more attempts or expensive human checking. Conversely, a higher-priced model can be cheaper per completed task if it succeeds quickly. Buyers need the full denominator: cost per accepted outcome.
Algorithmic progress offers a separate efficiency measure. Ho and colleagues estimated that compute needed for a fixed performance threshold halved roughly every eight months in their 2012–2023 language-modelling sample, with a wide confidence interval. They also found that increased compute contributed more to progress over that period. The result supports efficiency gains without establishing that scale stopped mattering, or that the historical rate applies uniformly to today’s frontier tasks. Algorithmic progress in language models.
This is also why cheaper inference can coexist with rising training and infrastructure expenditure. One measures the price of serving a particular capability; the other funds new capability and greater demand. The infrastructure article keeps those accounting boundaries separate.
Where value might accumulate
Where might durable value accumulate?
A competitive scenario, not a forecast that model capability becomes interchangeable.
Consider a model that can draft a purchase order. The organisation still needs the correct supplier data, permitted access to its systems, approval rules, reliable execution and an audit trail. The text-generation step is only one part of the service.
That suggests several possible advantages: proprietary data that improves decisions; distribution that brings users; workflow integration that saves effort; domain expertise that identifies failure; verification that makes results dependable; security and trust that permit deployment; infrastructure that delivers predictable service.
These are hypotheses about value, not guarantees of profitability. An integration can be copied. A dataset can become stale. Switching costs can preserve revenue without improving outcomes. Buyers should distinguish a useful advantage from dependence they cannot easily escape.
Can intelligence be compiled?
Earlier articles separated the gains from better chips, more training compute and better organisation of computation. Those gains open another possibility: the largest model may help produce the smaller model that ultimately serves the user.
Call this the frontier model as an intelligence foundry. It is an editorial framing, not an established technical term. The proposed architecture is frontier model → specialist training signal → smaller domain model → local or private deployment, where licences and deployment rights permit it.
An organisation cannot ask a transformer to extract its “Java neurons”, “clinical neurons” or “R neurons”. Learned representations are distributed and overlapping; a profession is not a detachable compartment. The warehouse article explains this distinction. But a teacher can generate examples from which a student learns a narrower competence. Classical knowledge distillation established the broader teacher–student approach; modern language-model pipelines can use generated answers and explanations as supervision.
The distinction matters commercially. Buying answers and building a reusable capability are different activities, even when both begin with the same model API.
Distillation, fine-tuning and retrieval do different jobs
| Technique | What changes | What it does not establish |
|---|---|---|
| Supervised fine-tuning | Updates a base model from task examples; can improve format, tone, task-following and domain behaviour | The model does not automatically become smaller or reliably factual |
| Continued pre-training | Adds learning from domain text before or alongside task adaptation | Familiarity with terminology is not validated professional competence |
| LoRA and adapters | Train a smaller set of additional or low-rank parameters around a base model | Fewer trainable parameters does not remove the base model needed at inference |
| Distillation | Uses teacher signals to train a student, potentially much smaller | A student is not guaranteed to match or beat its teacher |
| RAG | Retrieves external evidence at inference time | Retrieval does not guarantee that the evidence is correct or used faithfully |
| Quantisation | Reduces numerical precision and memory requirements | It does not itself create domain expertise |
| Pruning | Removes selected weights or structures | Speed gains depend on the resulting structure, hardware and software |
These approaches overlap. Distillation can use supervised fine-tuning as its training method; a distilled model can use retrieval and then be quantised for deployment. Domain adaptation research, LoRA, RAG, GPTQ and SparseGPT provide distinct technical foundations. They should not be collapsed into a single promise of compression without loss.
Java
Problems and candidate solutions
↓ Compiler, independent tests and security checks
Small Java modelClinical coding
Synthetic workflows and expert examples
↓ Trusted terminology, guidelines and qualified review
Small clinical specialistR
Analysis tasks and candidate scripts
↓ Executable tests and statistical review
Small R model↓ Independent evaluation → local or private deployment where justified
The largest model may not be the model that ultimately serves the user. It may become the machine that manufactures smaller intelligences.
The same pattern could support a pharmaceutical research assistant, a legal-domain specialist or an organisation-specific technical assistant. These are proposed applications, not claims that the diagram validates any of them. Each needs a defined operating boundary and an evaluation appropriate to its consequences.
Why could the smaller model perform better?
If bigger models are smarter, why could a smaller model ever perform better? Because a production task is narrower than general intelligence. Concentrated training, less ambiguity, precise objectives, repeated exposure to domain edge cases and stronger verification can improve performance within that boundary. In editorial terms, the student exchanges breadth for density of competence.
The comparison must be fair: use unseen cases, comparable access to tools and evidence, and a declared cost or latency budget. A specialist beating a weakly prompted teacher on one benchmark does not show that it is generally superior.
Distilling Step-by-Step used teacher-generated rationales as additional supervision and reported smaller students outperforming prompted larger models on specific NLP benchmarks. That is evidence for a particular method and evaluation setting, not a guarantee for every domain. Generated explanations are training signals; they are not authenticated records of a teacher’s internal reasoning.
The student need not inherit the teacher’s average performance. It can be trained on the teacher’s best work.
“Best” still needs an independent definition. Filtering can concentrate useful examples, but a faulty verifier can select convincing mistakes. A curriculum also needs hard cases and coverage of failures, not merely the easiest examples that pass.
Java: generate broadly, verify independently
A teacher could generate programming problems, working solutions, deliberately broken solutions, concurrency errors, refactoring tasks, Maven projects, Spring examples, unit tests, code reviews and production incidents. The training record should distinguish a known broken example from a solution approved for use.
Compilation and mvn test provide concrete checks. Static analysis, linters, security checks and integration tests add other evidence. Tests authored by the same teacher should not be the only judge: independent specifications and withheld tests help avoid a solution and its test sharing the same error. Concurrency and security failures may survive an ordinary test suite.
Synthetic data becomes much more powerful when its correctness can be independently verified. A smaller model can know less, yet perform better — if we know exactly what we need it to know, and test whether it does.
Clinical coding: separate reasoning from evidence
A clinical specialist should not simply inherit whatever a frontier teacher remembers. One proposed workflow starts with synthetic cases and expert-labelled examples, then checks candidate outputs against the relevant ICD-10 edition, licensed SNOMED CT, validated terminology, medication knowledge and current clinical guidelines. Knowledge graphs can make relationships explicit. De-identified records may be useful only where their use is legally and ethically appropriate; de-identification alone does not settle that question.
SNOMED CT access and use are subject to its licensing arrangements. The coding system, jurisdiction, source version and intended clinical use must be explicit. Qualified review remains necessary; a plausible code or citation is not proof of correctness.
The proposed specialist need not memorise all medicine. It needs enough competence within its operating domain to retrieve authoritative information, apply it appropriately and escalate uncertainty. Keeping the reasoning model and evidence source separable makes updates and auditing more practical. It does not, by itself, establish clinical safety or regulatory approval.
Model intelligence is not system intelligence
Consider a small specialist that retrieves evidence and terminology, generates a candidate, verifies ontology relationships, runs a contradiction check, performs a second pass and returns evidence with uncertainty. If each step is inexpensive enough, that workflow might fit within the cost or latency budget of one frontier response. This is a design hypothesis to benchmark, not a measured speed claim.
The strongest production system may therefore use a smaller individual model. Conversely, adding many weak model calls can compound errors. The test is the complete workflow: accepted outcomes, failure severity, latency and total cost. Local inference tools such as llama.cpp make deployment technically possible for supported models, but available memory, context length, concurrency and the model licence still determine what is practical. Open weights do not mean unrestricted use or full ownership.
The enterprise dependency problem
If an essential capability exists only behind somebody else’s API, the organisation does not own that capability — it rents access to it. It may own its surrounding application and data, while remaining dependent on the provider to supply the model behaviour.
This is an ordinary supplier risk. Models are retired; APIs are deprecated; prices, contracts and behaviour change. Rate limits, regional availability, outages, acquisitions, strategic changes, regulation and concentrated infrastructure can all affect service. Provider deprecation schedules make lifecycle change a concrete engineering concern, without requiring a prediction of corporate failure.
A resilience review would question a critical system with one database, one region, an undocumented interface and no recovery plan. It should also question one proprietary model, one expected behavioural profile, no tested alternative and no fallback. A local model adds little resilience if it still depends on the same unavailable retrieval service or identity system.
The Model Continuity Plan
We use Model Continuity Plan as an editorial name for applying recovery planning to AI-dependent workflows. Its scope should follow the importance of the service.
- Keep prompts, schemas and orchestration portable where practical, while documenting provider-specific behaviour.
- Maintain an independent evaluation suite and a governed domain corpus with documented rights.
- Test at least one alternative model or provider through a compatibility layer.
- Rehearse replacement, monitor drift and define migration, rollback and escalation responsibilities.
- Where economically justified, maintain a local or open-weight specialist and the ability to rebuild it.
- Define the minimum acceptable service during disruption, including tasks that must stop or move to human review.
For illustration only, imagine normal operation at 97% task success, a local fallback at 93%, and no automated service at 0% during an outage. These are invented figures, not a benchmark. They illustrate continuity value; they do not establish that a four-point decline is acceptable. In a safety-critical workflow, the fallback may need a narrower remit or mandatory review. A manual service may also be a better alternative than either model.
Does your AI architecture have an exit strategy?
The practical questions are specific. What happens if this model is retired? Can another provider run the workflow? Do we know how it compares? Do we control the evaluation data and have rights to enough examples to specialise a replacement? Can we operate during migration? Which workloads could run locally, and which capabilities are genuinely vendor-specific?
The objective is not the smallest model. It is the smallest model that reliably retains the intelligence required for the job. Sometimes the best answer will remain a frontier API.
Distillation as financial optionality
At sufficient volume, compare API expenditure across millions of calls with the full cost of data preparation, teacher generation, distillation, hardware or hosting, local inference, evaluation, security, maintenance and human oversight. Include utilisation, retries, refresh cycles and the cost of failures. A cheap token is not necessarily a cheap accepted result.
Frontier APIs remain attractive for low volume, highly varied work, complex reasoning, rapidly changing tasks and organisations without the engineering capacity to operate models. Specialists become interesting where work is frequent, repetitive, narrow, latency-sensitive or privacy-sensitive. Local hosting brings its own security and operational duties.
Distillation optionality means preserving the ability to make that choice later. It does not require leaving a provider today. Nor does it establish that every organisation should train a model.
Preserve the experience before you need it
An organisation cannot suddenly decide years later to distil a specialist if it discarded the examples that define good performance. Important deployments should consider distillation-ready operations: deliberately preserving selected, governed evidence of how work was done.
The useful Organisational AI Experience Record is more than prompt → response. It connects the task and input, retrieved context, system configuration, provider and model version, answer, tools and actions, user decision, correction, acceptance or rejection, and the eventual outcome. Some fields may need redaction, an access-controlled reference or omission.
Don’t just capture what the model said. Capture what happened to its answer.
Consider an engineer changing three lines before merging generated code. Those changes may encode an important correction, but the reason and tests are needed to interpret them. A clinician selecting code Y instead of X and recording why creates a different sort of labelled example. A lawyer correcting a clause classification, or a support agent changing a resolution whose result is later known, adds evidence that raw generations lack. Acceptance alone is not proof: users can miss errors and outcomes can have other causes.
Where appropriate, retain the provider, model family and version; system prompt version; temperature and relevant inference settings; retrieval configuration and evidence versions; tool calls; output schema; corrections and outcomes. This supports investigation, though hosted model changes and nondeterminism may prevent exact reproduction. Do not collect hidden internal reasoning or sensitive material merely because more metadata might be useful someday.
Govern the record, do not log everything
Patient data, personal identifiers, employee information, legal privilege, confidential corporate material, source-code secrets, financial information and copyrighted works require deliberate controls. A production logging policy is not automatically a permission to train. Purpose, lawful basis, consent where required, access, licensing, contracts, retention obligations and deletion must be assessed before reuse. The ICO’s data-minimisation guidance requires personal data to be limited to what is necessary for its purpose.
Use an explicit sampling policy, sensitive-data filtering, purpose and rights checks, retention rules and quality review. Agree the legal basis before collection; filtering afterwards cannot repair an unlawful collection. Preserve useful organisational AI experience deliberately, not indiscriminately.
Provider outputs are not automatically available for distillation. Check the applicable contract, service terms, output-use restrictions and student-model licence. Anthropic’s commercial terms, for example, restrict using services to build a competing product or service, including training competing AI models, unless expressly approved. A provider-supported workflow may grant specific permissions; it does not authorise arbitrary exports or training elsewhere. Recheck the terms at implementation time.
Keep the test separate from the lesson
↓ Sampling → sensitive-data filtering → rights and retention checks → quality review
Independent evaluation
Held-out ordinary cases, edge cases and failures
Test a replacement provider or modelPermitted training corpus
Curated examples with provenance and corrections
Specialise a model where justifiedSeparate datasets and access rules. Shared source cases must not leak between training and evaluation.
Do not send every retained example into training. Reserve independent evaluation sets containing ordinary cases, difficult cases, production failures, edge conditions, rejected answers, safety-critical scenarios and adversarial examples. Prevent related records, such as versions of the same case, from leaking across the split. If an evaluation failure becomes a training example, replenish the independent test.
The organisation should own the test of whether a replacement is acceptable. Model portability requires evaluation portability. Record evaluation versions and thresholds, review error severity and repeat checks after changes. The NIST AI Risk Management Framework provides a broader basis for lifecycle measurement, governance and monitoring; the continuity and experience-record concepts here are our proposed application of that discipline.
The organisational AI moat
A company’s asset may become more than prompts, documents, a vector database and an API key. Real tasks, attempts, accepted and rejected outputs, human corrections, tool traces, edge cases, outcomes and failures can form a corpus describing how that organisation works. Governed subsets support evaluation of a new vendor and training of a specialist, with different access and usage rules.
The companies that preserve their AI experience may eventually own something the frontier provider does not: a model of how their organisation actually works. Here “model” first means a useful representation of practice, not necessarily trained neural weights. The provider may know more about medicine, law or software generally. The organisation may know more about how this particular team performs this particular job.
Imagine, purely illustratively, 10,000 high-quality examples in year one, 100,000 with corrections in year two and 500,000 with outcomes and edge cases in year three. These are not targets or predictions. Quality, coverage, permissions and freshness matter more than the count. A later competitor faces the question: trained on what? Historical labelled experience can be difficult to reconstruct, but a growing archive of biased or obsolete decisions is a liability rather than an advantage.
Renting intelligence, manufacturing competence
Why rent a trillion-parameter generalist every time you need a three-billion-parameter specialist? Those parameter counts are illustrative; they describe no undisclosed commercial model. The question only makes sense after proving the smaller system can meet the requirement.
A customer may want to rent frontier capability temporarily, generate permitted and verified experience, then move routine work to a specialist. A provider may value continuing inference revenue. That creates a possible economic tension, not an inevitable conflict. Providers can sell distillation, fine-tuning, hosted specialists, evaluation, orchestration, private deployment and lifecycle management.
Amazon Bedrock Model Distillation already illustrates a provider-supported teacher–student service. Its existence supports the foundry analogy; it does not mean every resulting model can be downloaded or run locally. Hosting arrangements and portability rights remain part of the purchasing decision.
What does this mean for frontier companies?
A provider can participate in both sides of this transition: serving difficult requests directly and helping customers produce specialists for routine work. Bedrock’s documented service is one concrete example. The wider commercial proposition is an inference: customers may pay for the curriculum, evaluation, deployment and maintenance around a model as well as for its answers.
A durable advantage could be the combination: model, platform, ecosystem, data, tools, distribution and infrastructure. Owning the best model could still matter, especially on high-value tasks with difficult thresholds. Owning it may also be insufficient if rivals deliver comparable outcomes through cheaper systems.
History offers questions, not a script
The transitions from mainframes to personal computers, servers to cloud services and proprietary software to open-source alternatives provide useful comparisons. In each case, ask which layer became more widely available and which surrounding activities customers continued to pay for.
They do not establish that AI must commoditise. Cloud computing also demonstrates how widely accessible capability can be delivered through concentrated infrastructure. Availability and decentralised ownership are different outcomes.
The strongest test of this edition’s economic proposition is therefore not whether models become cheaper. It is whether customers can substitute one complete service for another without losing something they value. If they can, the model’s scarcity weakens. If the trusted system remains hard to reproduce, value may persist around it.
Start with one workflow
Choose a frequent, bounded task with a clear definition of success. Establish the current cost per accepted outcome, identify the rights and privacy constraints, and reserve an independent test set. Capture a small, reviewed sample of corrections and outcomes under an explicit retention policy. Then compare a replacement API and, where feasible, a specialist against that same test.
Set a decision rule before running the comparison: required quality, unacceptable failures, latency, total operating cost and recovery time. Include human fallback and the cost of maintaining the alternative. The result may justify distillation, a second provider, better retrieval, or simply better evaluation of the existing service. Each can improve the organisation’s ability to make an informed choice.
An ecosystem of specialised intelligence
The business could evolve towards inference utilities, intelligence foundries, orchestration platforms, evaluation and lifecycle services, private deployment infrastructure, or combinations of them. We do not know which model wins. Better teachers, distillation, verification, retrieval, orchestration and specialists expand what AI scale can mean beyond parameter count.
Perhaps the future is not one ever-growing digital brain answering every question. Perhaps the largest models increasingly become teachers, producing smaller intelligences that organisations can deploy, control and combine. If that happens, one valuable asset to start building today is a carefully governed record of what the organisation’s AI has attempted, what people corrected and what actually worked.
Technical research and governance sources are linked below. Commercial terms and the provider-supported distillation example were rechecked on 25 September 2026. The foundry and continuity concepts are editorial proposals; numerical scenarios are illustrative.